Copilots & assistants
In-app assistants that understand your product and your user.
We turn language models into dependable product features: copilots inside your software, generators for content, and tools that summarise, classify and extract at scale.
We agree what good output looks like, using real examples.
Prompts, tools and output formats are built around your data.
We pick the model that fits the quality, speed and cost you need.
Validation, retries and fallbacks catch bad or off-format output.
Evals and usage tracking keep quality and spend in check.
In-app assistants that understand your product and your user.
Structured prompts, function calling and model selection for cost and quality.
Models tuned on your data for tone, format or domain accuracy.
Turn emails, forms and documents into clean, structured data.
OpenAI, Anthropic, open-source and self-hosted models behind one API.
Caching, routing and streaming keep responses fast and affordable.
 SaaS
Users ask for reports, drafts or settings changes in plain language.
Your app→Copilot→Actions Marketing
On-brand product descriptions, emails and posts generated and reviewed in one flow.
Catalogue→Brand voice→CMS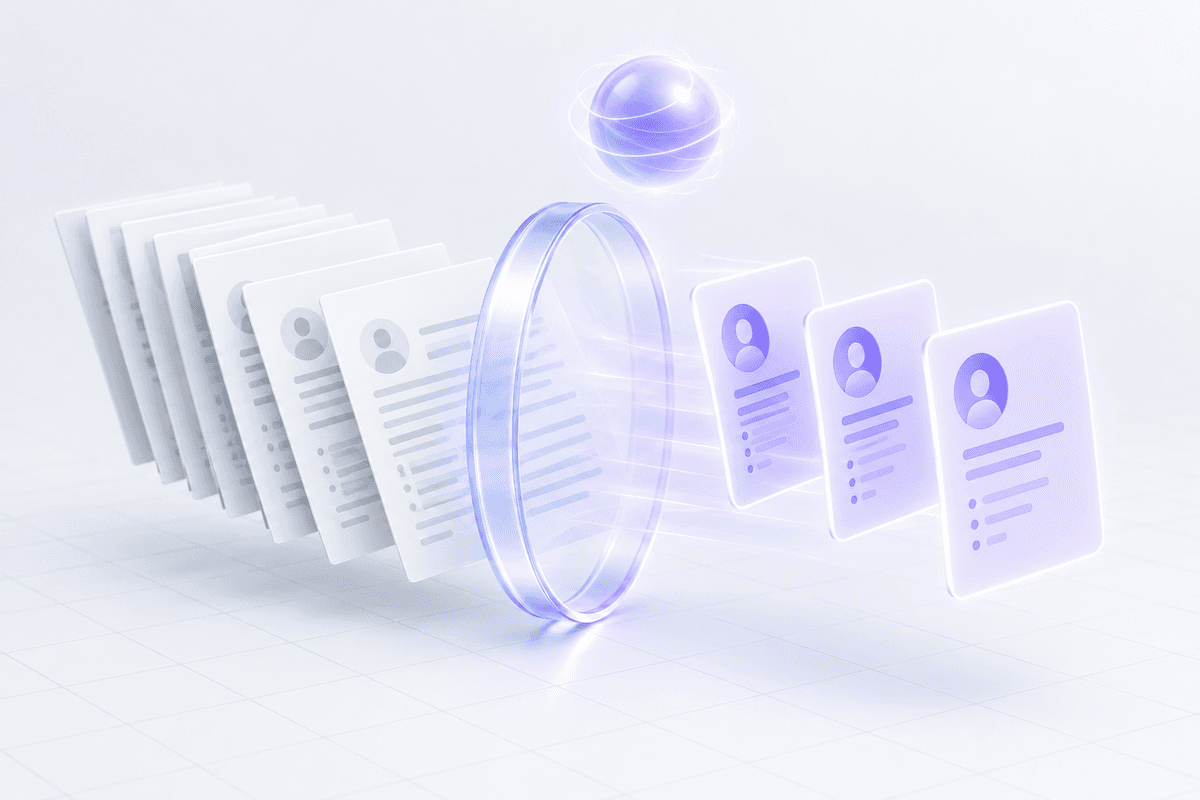 Recruitment
CVs and interviews summarised into structured, comparable scorecards.
CVs→LLM→Scorecards| Capability | Manual work | Generic chat tool | Custom LLM feature |
|---|---|---|---|
| Works inside your product | No | No | Yes |
| Uses your data and rules | Yes | Partly | Yes |
| Consistent output format | Varies | No | Yes, validated |
| Handles thousands of items | No | Copy and paste | Yes, in batches |
| Quality and cost tracked | No | No | Yes |
 Content engine
An AI content platform that writes blog posts and website copy in 25+ languages across 50+ content types.
A chatbot, voice agent and Chat LLM workspace that compares answers from leading models side by side.
AI mockups, proposals and plan reading for sign and graphics professionals.
A short workshop to pick the use case, define what success looks like and check your data.
A working demo on your real data within weeks, so you can see it before you commit.
A production build connected to your tools, with guardrails, tests and monitoring.
We go live, track quality and cost, and keep tuning as usage grows.